Tech Vaidya WhatsApp Channel
Get AI updates, tech news, cybersecurity alerts and useful tech tips directly on WhatsApp.
Nagaraj Vaidya
Tencent’s launch of a new AI model has once again stirred the global AI industry. Called Hy4 Preview, the model is reportedly built with a massive 770 billion parameters, making its sheer scale one of the biggest talking points around the release. But it would be misleading to look at that number and conclude that the model is automatically five times more intelligent than the AI models people commonly use today. Its real significance lies not simply in its size, but in the way that enormous capacity can be selectively activated when a task requires it.
The release becomes even more interesting because Hy4 Preview is being made available as an open-source model. Tencent says it is intended for demanding workloads such as coding, research and financial analysis. That means this is not merely an experiment designed to showcase a large parameter count; it is a large AI model that developers can actually explore and test within their own environments. But before discussing what it can do, there is a more fundamental question to answer: what does 770 billion parameters actually mean?
The number of parameters in an AI model is not a direct measurement of its intelligence. Parameters are numerical components that represent the relationships a model learns during training. A larger parameter count can indicate greater capacity, but it does not guarantee that the model will perform better at every task. In AI, size matters, but architecture, training, reasoning ability, efficiency and the way the model uses its capacity matter just as much.
What exactly is inside those 770 billion parameters?
Hy4 Preview uses a design known as MoE, or Mixture of Experts. One simple way to understand this architecture is to imagine a large hospital with hundreds of doctors. When a patient walks in, all those doctors do not examine the patient together. The patient is directed to the specialists relevant to the particular problem.
MoE works on a similar principle. Although the model has a total capacity of 770 billion parameters, it does not necessarily need to activate that entire capacity for every query. Instead, the system can activate the parts that are most relevant to a particular task, helping control the amount of computation and resources required. According to the specifications associated with Hy4 Preview, around 49 billion parameters are active for a given query.
That does not mean Hy4 Preview will always outperform every 49-billion-parameter model. The important point is that MoE allows a very large amount of overall capacity to exist within one model while using only a portion of it when needed. That combination of scale and selective activation is one of the reasons MoE architectures have become increasingly important in the development of large AI models.
 AI Isn’t Just Learning to Hack. It Is Learning to Find Its Own Way to the Goal
 Is AI Becoming a Hacker? The New Cybersecurity Threat Emerging From AI Agents
 Why OpenAI, Microsoft, Meta, and NVIDIA Are Speaking With One Voice on Open-Weight AI
 The Next Big AI Security Threat May Not Be the Model—It May Be the Skills You Install
 A 30 Billion Dollar Bet: Rewriting India's Cloud Infrastructure
Another notable capability of Hy4 Preview is its ability to handle a context of up to one million tokens. In practical terms, this means developers can potentially provide a very large amount of text or code to the model in a single context. For tasks involving large documents, extensive codebases or multiple files that need to be understood together, such a large context window can be extremely useful.
But there is an important distinction here. Having a huge context window does not automatically mean that a model will understand every piece of information inside it equally well or without mistakes. Taking in a large amount of information is one capability; identifying the information that actually matters and using it correctly is another. In real-world applications, the second ability may prove far more important.
From writing code to understanding entire projects
Tencent is also integrating Hy4 Preview into products such as CodeBuddy and WorkBuddy. This reflects a broader shift in how AI is being used in software development. The role of AI is moving beyond simply suggesting the next line of code toward agents that can understand larger parts of a project and assist with multi-step tasks.
Imagine a large software project where the payment module needs to be made more secure. A conventional coding assistant might examine a particular file and suggest changes. A more capable AI agent, however, could potentially inspect the relevant parts of the entire project, identify which files may need modification and suggest the necessary code changes across multiple components.
This is where the model’s intelligence becomes only one part of the equation. Its permission boundary becomes equally important. Is the AI allowed only to read the code? Can it suggest changes? Can it actually modify the code? Or does it have permission to change the code and upload it directly to a production server? These three situations carry very different levels of risk.
This is not a question specific to Hy4 Preview. It is becoming a fundamental issue for the next generation of AI agents. As AI systems become capable of taking multiple steps on their own, what tools they can access and what they are allowed to change in the real world may become more important than how impressive their benchmark scores look.
What could this mean for developers in India?
The open-source availability of Hy4 Preview makes the release particularly interesting for developers in India and elsewhere. Until recently, many of the most powerful AI models were primarily accessed through cloud services. Developers would send their data to an external platform, have the model process it and then receive the result.
Open-source models create a different possibility. Organisations can evaluate the model in their own environments, explore how it fits their infrastructure and potentially adapt it for specific workloads. For companies dealing with sensitive source code, internal documents or proprietary information, having greater control over where and how a model operates can be particularly valuable.
However, the word “free” needs to be understood carefully. Even if a model can be downloaded or accessed without a conventional licensing fee, running a model of this scale can require substantial computing resources, GPU capacity, storage, electricity and ongoing infrastructure management. Open source does not mean that everyone can simply run a 770-billion-parameter model effortlessly on an ordinary laptop.
That is why the more useful question for developers is not “Can I get this for free?” but “Do I actually need it?” A small code modification or basic text-processing task may not justify using a massive model. On the other hand, large codebases, complex research tasks and extensive document analysis could benefit from a model with a large context window and substantial overall capacity.
Beyond the China-US AI race
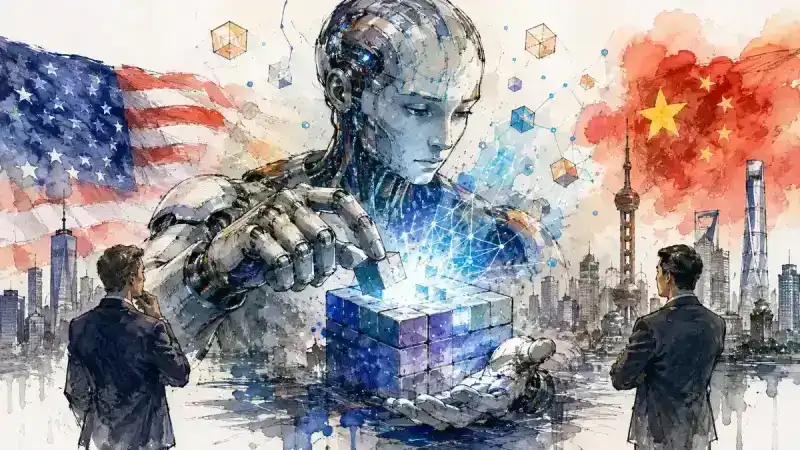
Tencent’s release will inevitably bring the China-US AI competition back into the conversation. China is continuing to strengthen its position in the global AI race through large models, advanced computing infrastructure, powerful chips and open-source releases. But from a developer’s perspective, the more important question is not which country wins the race. It is what developers can actually do with the technology becoming available to them.
When a model is described as having 770 billion parameters, the size of the number naturally grabs attention. But the AI industry is gradually moving toward a more complicated set of questions. How efficiently can a model use its capacity? How quickly can it respond? How well can it reason? How much context can it handle? What tools can it work with? And how much does it cost to operate? These questions may ultimately matter more than parameter count alone.
Hy4 Preview is also still a Preview release. In some difficult tasks, it may reportedly spend more time than necessary and repeatedly reconsider its own answers. That is an important reminder that this should not be viewed as a finished, flawless product. It is better understood as an example of the direction in which large AI models are evolving.
And that is where the real significance of this release lies. The AI race is no longer simply about asking, “Whose model is bigger?” It is increasingly about how much capability can be delivered efficiently, how developers can access that capability and how much autonomy AI systems should be given. Hy4 Preview illustrates that shift clearly.
Seven hundred and seventy billion parameters is an enormous number. But that number alone will not determine the model’s future. Its architecture, performance, context handling, operating cost and, above all, the problems developers use it to solve will determine its real value.
Big numbers will always make headlines in the AI industry. But for a developer, the more important question is a much simpler one: What can I actually build with all that capability?
The answer to that question will ultimately determine what Hy4 Preview is really worth.

No Comment Yet.
Stay informed with breaking news, trending stories, and in-depth analysis.